
OpenAI Agents API Public Beta: Run the Codex Harness Behind Your Own Agents with a Single API Call
OpenAI opened the public beta of the Agents API on September 10, 2026. If you’ve been building your own agent orchestration layer, or you’ve been slowed down by context compaction, tool scheduling, or parallel subagent management in sandboxes, this article covers exactly what it takes over and what you still need to configure yourself.
What Do You Actually Need to Write in a Single API Call?
The question is straightforward: what’s the minimum set of fields required to create a working cloud agent?
The official JavaScript example puts four things together: task, model, tools, and environment.
import OpenAI from "openai";

const client = new OpenAI();

const session = await client.beta.agents.sessions.create({
  agent: {
    model: "gpt-6-astra",
    tools: [
      {
        type: "mcp",
        server_label: "observability",
        transport: {
          type: "http",
          server_url: "https://observability.example.com/mcp",
        },
      },
    ],
    multi_agent: { enabled: true, max_concurrent_subagents: 3 },
  },
  vault_ids: ["vault_YOUR_VAULT_ID"],
  environment: {
    type: "openai_hosted",
    capability_directories: ["/workspace/capabilities/skills"],
  },
  input:
    "Investigate service-api's elevated 5xx rate over the last 30 minutes. " +
    "Delegate deployment, error, and dependency analysis to subagents. " +
    "Save findings, evidence, and recommended mitigation in /workspace/outputs.",
});
agent.model takes the model ID. agent.tools is an array — the example attaches one MCP server with transport.type set to http and server_url pointing to that server’s address. multi_agent.enabled turns on subagents, and max_concurrent_subagents controls how many run in parallel.
vault_ids is an array of vault IDs. The agent pulls sensitive credentials from here at runtime instead of hardcoding secrets in environment variables.
The environment block decides where the agent’s code runs. The example uses openai_hosted, meaning an OpenAI-managed sandbox, and capability_directories mounts a skills directory so the agent can read those files inside the sandbox.
input is a natural-language task description. The example task investigates an elevated 5xx rate on service-api over the past 30 minutes, delegates deployment, error, and dependency analysis to subagents, and writes findings, evidence, and recommended mitigation to /workspace/outputs.
That input is worth reading twice. The task description already contains the subagent分工 — in other words, orchestration intent is expressed through the prompt, not hardcoded as a task graph in code.
Which Sandbox Should You Choose? Three Options
Different workloads have different requirements for compute, storage, and deployment location. The Agents API makes the environment a swappable layer with three paths.
The first is an OpenAI-hosted sandbox. OpenAI provisions and manages it, using the same sandbox infrastructure that powers Codex and ChatGPT. You can load files, packages, skills, and plugins into it, and the agent runs code, works with files, and produces artifacts inside. If you want to get started quickly without maintaining infrastructure, take this path.
The second is running compute on your own infrastructure. The official architecture shows an application sending tasks to the Agents API, the Agents API running the managed Codex harness, the harness sending tool calls to a sandbox and receiving tool results, while self-hosted compute stays under your control.
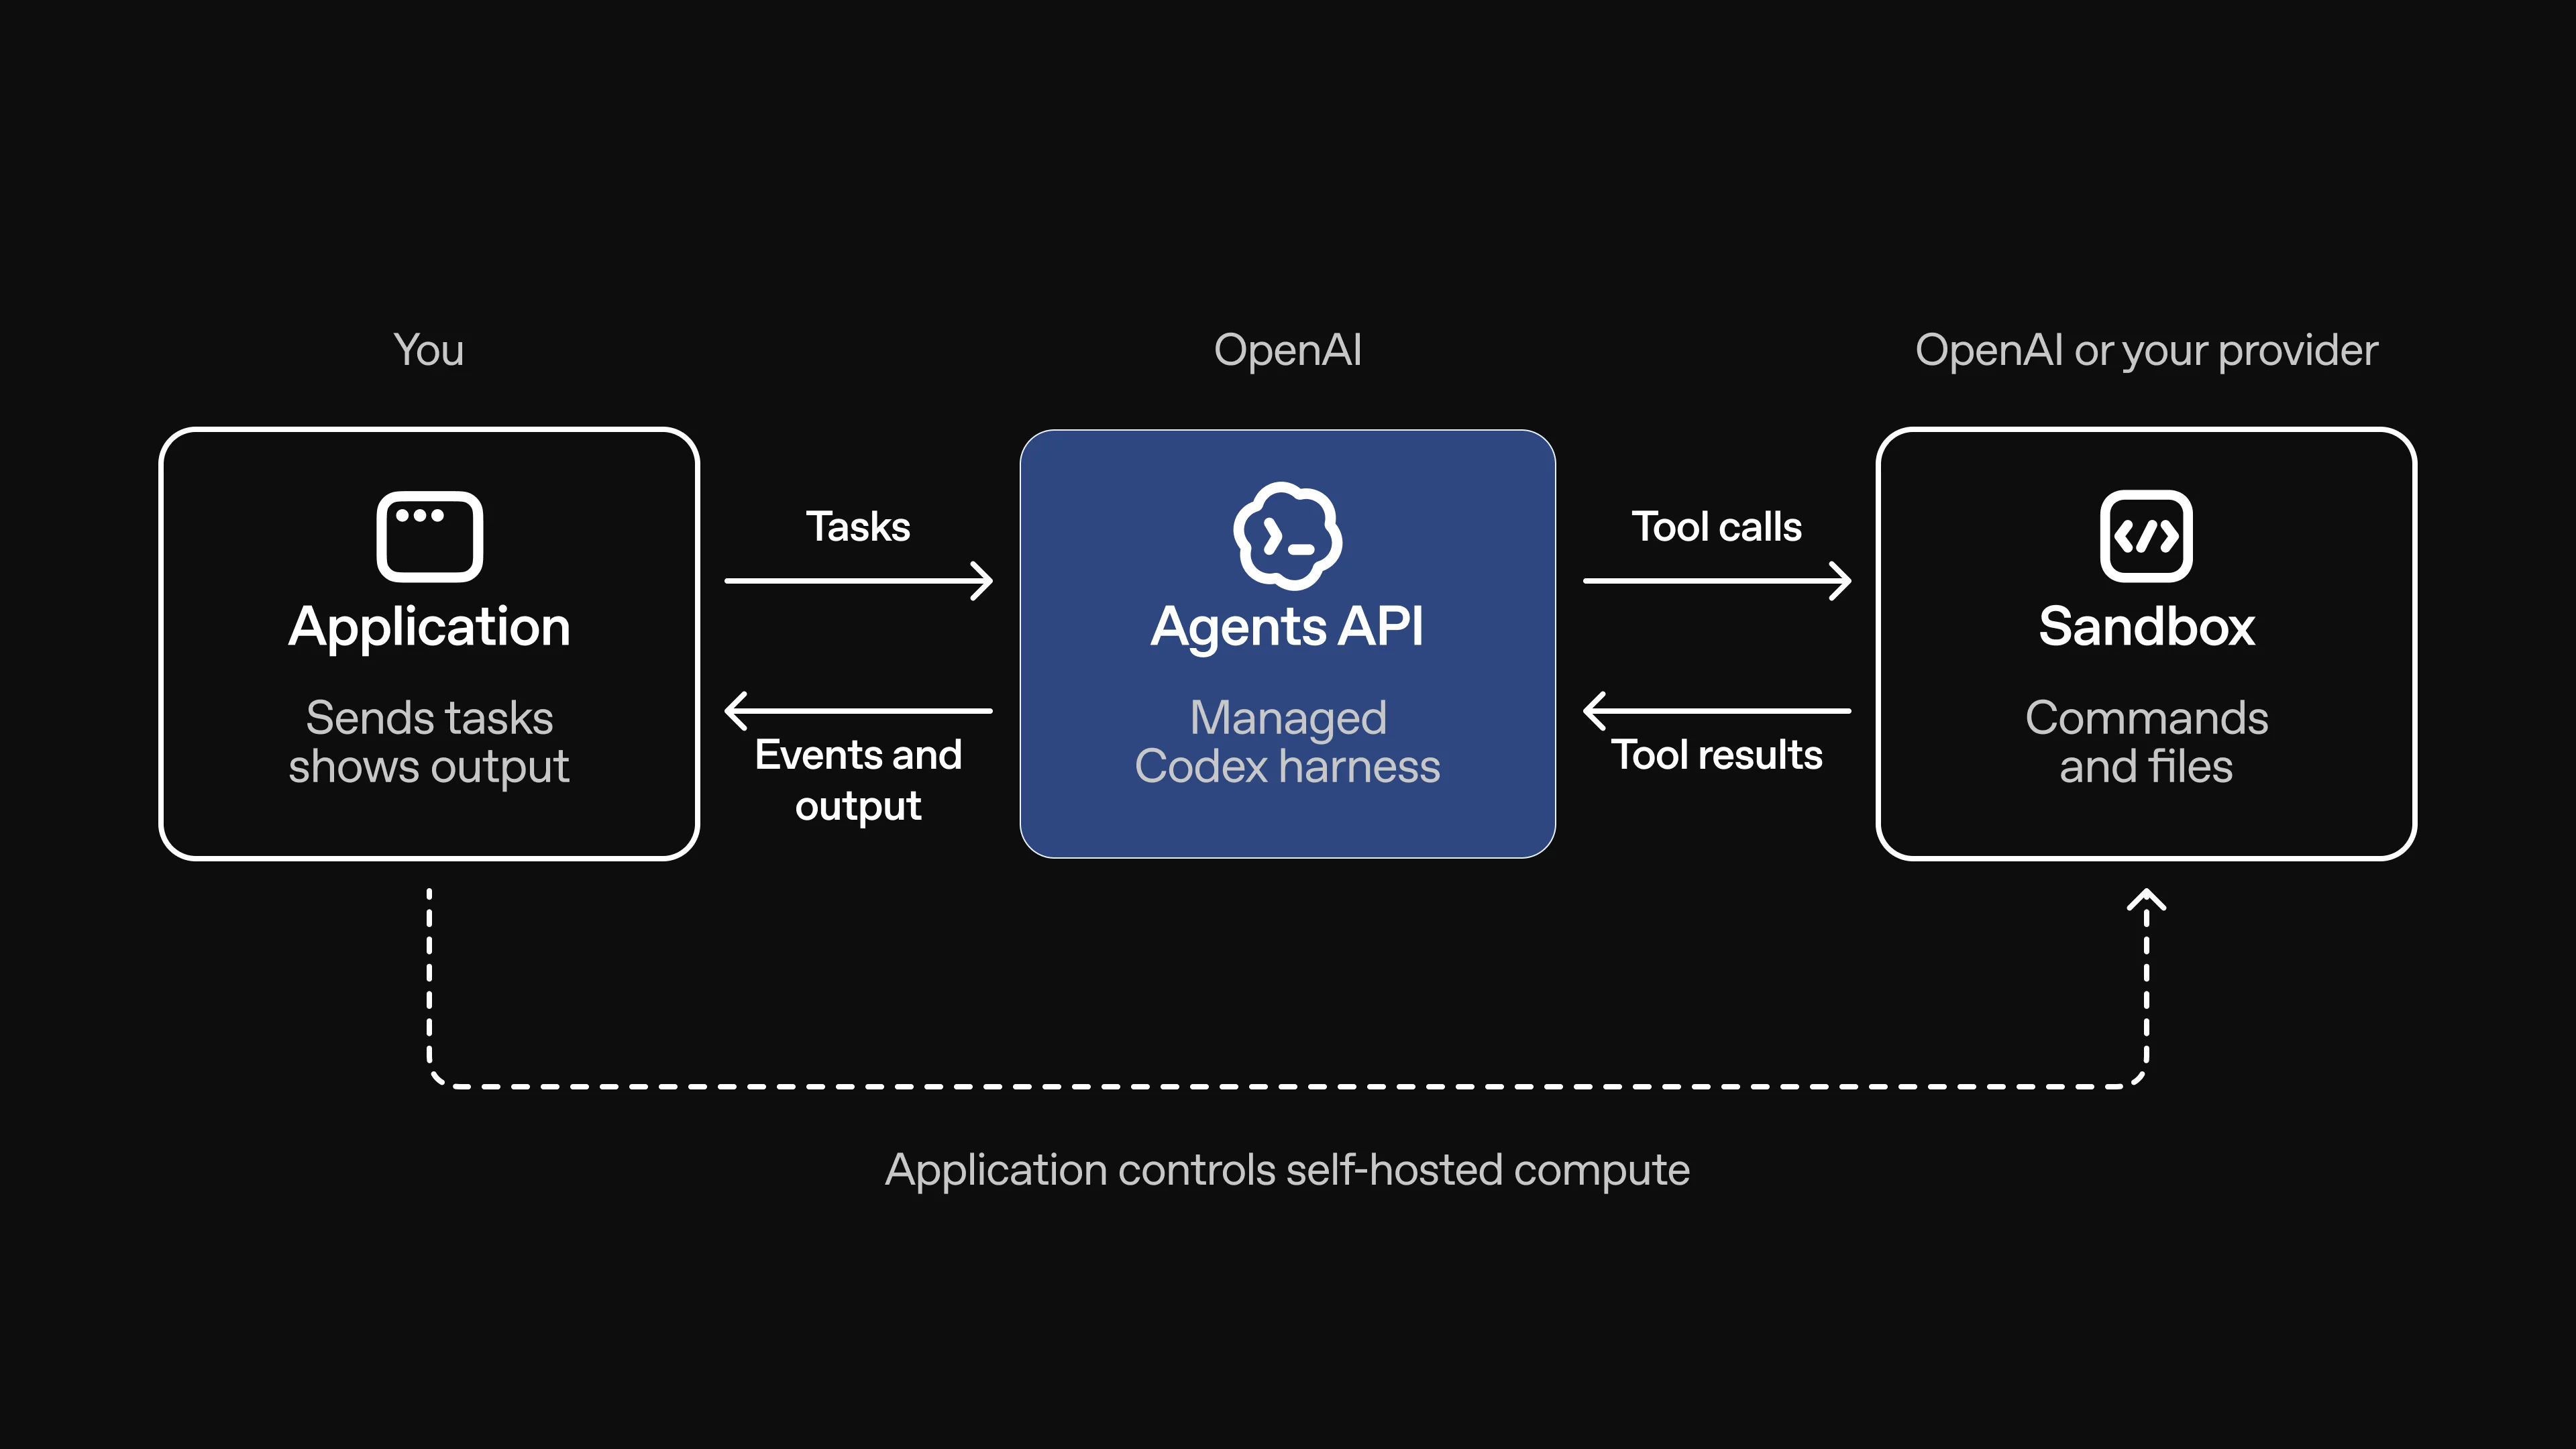
The Agents API powers your agents with the same harness and infrastructure behind Codex.
The third is going through sandbox partners. OpenAI’s current partners include Blaxel, Cloudflare, Daytona, DigitalOcean, E2B, Modal, Oracle, Runloop, and Vercel. These integrations cover several categories of needs: fully managed deployments or deployments inside your VPC, specific file and secret storage mechanisms, different CPU, GPU, and memory configurations, and different performance, cold-start, and cost profiles.
The Agents API offers first-class integrations with popular ecosystem providers.
Your choice comes down to three things: latency requirements, cost requirements, and where your data must stay. The documentation doesn’t break down each partner’s specific differences, but it gives you a direction. If you need GPUs or a specific secret-management approach, you’ll find a match among the partners. If you just want to get something running, the hosted sandbox is the least effort.
What Engineering Headaches Does the Harness Take Over?
Anyone who has built an agent knows that model capability is only part of the story — the rest is engineering. The Agents API harness handles several specific areas, and it keeps updating as models improve. That last point matters more than any single feature, because you don’t have to rebuild your orchestration layer every time a new model ships.
What Happens When a Long Session Fills Up the Context Window?
An agent running for hours will eventually fill its context window. The harness automatically compacts earlier context as a session approaches its context limit, preserving the information the agent needs to continue. You can build workflows that span multiple context windows without implementing your own compaction logic.
The scenario here is concrete. An agent debugging a production issue might need to read dozens of log files, run several queries, and go back and forth with subagents a few times — intermediate output quickly blows past the window. Implementing compaction yourself means deciding what to drop and what to keep, and dropping the wrong thing means the agent gives wrong answers later.
Too Many Tools — How Do You Manage Tokens and Cache?
When tool definitions pile up, just stuffing every schema into the prompt consumes a large amount of tokens and hurts cache hits. The harness’s tool search loads relevant tool definitions on demand, reducing token usage and cost while preserving the model’s cache.
Once tools are available, programmatic tool calling lets agents run calls in parallel, chain related operations in code, filter and combine results, and bring only the relevant parts back into context. The difference is obvious with large volumes of data — you don’t have to stuff every raw result back into the model context.
The Agents API supports three categories of tools: MCP, custom functions, and built-in tools like web search.
"agent": {
  "tools": [
    {
      "type": "mcp",
      "server_label": "openai_docs",
      "transport": {
        "type": "http",
        "server_url": "https://developers.openai.com/mcp"
      }
    },
  ]
}
Do You Need to Build Subagent Parallelism Yourself?
Multi-agent support lets the Agents API break complex tasks into independent pieces and delegate them to parallel subagents. Each subagent maintains its own context, stays focused on its assignment, while the main agent coordinates and brings results together.
The configuration is just a few lines.
"agent": {
  "model": "gpt-6-astra",
  "multi_agent": {
    "enabled": true,
    "max_concurrent_subagents": 3,
  }
}
max_concurrent_subagents controls the concurrency limit — set it based on your task and cost. This structure speeds up research, analysis, and coding tasks that naturally parallelize, and it saves you from building your own orchestration.
Jack Weissenberger, CTO of Ciridae, shared some numbers in the announcement. After adopting the Agents API, their evaluation score went from 0.71 to 0.85, and latency dropped by 4x. He also mentioned that observing and orchestrating subagents in their old setup was cumbersome, and the new API made subagent flows an out-of-the-box lift.
What Does the Open-Source Foundation Mean?
The Agents API runs on the open-source Codex harness. The core logic that coordinates model calls, tools, and context is public on GitHub at github.com/openai/codex. OpenAI operates and maintains the harness, and you can inspect how it’s implemented.
For developers evaluating whether this fits their team, that public codebase is something you can actually read through. For those who just want to get started, knowing the foundation is open source means you don’t have to treat it as a complete black box.
Pricing and How to Get Started
The Agents API is available in public beta to all developers. There are no additional API fees — you simply pay for the tokens and tools your agents use. Pricing is at developers.openai.com/api/docs/pricing.
To get running quickly, follow the quickstart. To see the full picture first, read the overview. During the public beta, OpenAI will iterate based on feedback on the path toward general availability.
Quick Reference
-
Create a session with client.beta.agents.sessions.create, declaring task, model, tools, and environment in one call -
agent.modeltakes the model ID — the example usesgpt-6-astra -
agent.toolsattaches an MCP server withtype,server_label,transport.type, andtransport.server_url -
vault_idstakes an array of vault IDs to avoid hardcoding secrets in environment variables -
environment.typeset toopenai_hosteduses the managed sandbox; you can also switch to self-hosted infrastructure or a partner -
capability_directoriesmounts a skills directory into the sandbox -
multi_agent.enabledturns on subagents;max_concurrent_subagentssets the concurrency cap -
Use natural language in inputto describe the task and delegation — orchestration intent is expressed through the prompt -
Context compaction, tool search, and programmatic tool calling are handled automatically by the harness -
Billing covers only tokens and tools — there are no additional API fees
FAQ
What’s the difference between the Agents API and calling the model API directly?
With the model API, you manage context, tool scheduling, and sandbox lifecycle yourself. The Agents API hands that layer to OpenAI’s managed Codex harness — you declare task, model, tools, and environment.
Are there extra charges during the public beta?
No additional fees. You only pay for the tokens and tools your agents use.
How many subagents can run at once?
Controlled by max_concurrent_subagents. The example uses 3. The documentation doesn’t specify a hard upper limit.
Can the sandbox run on my own servers?
Yes. There are three environment options: OpenAI-hosted sandbox, self-hosted infrastructure, and sandbox partners. The self-hosted path keeps compute under your control.
Which sandbox partners are available?
Blaxel, Cloudflare, Daytona, DigitalOcean, E2B, Modal, Oracle, Runloop, and Vercel.
What tool types are supported?
MCP, custom functions, and built-in tools like web search.
Will the agent break when the context window fills up?
The harness automatically compacts earlier context as a session approaches its limit, preserving what the agent needs to continue. You don’t write compaction logic yourself.
Is the underlying implementation closed source?
No. It runs on the open-source Codex harness, with core logic public at github.com/openai/codex.
